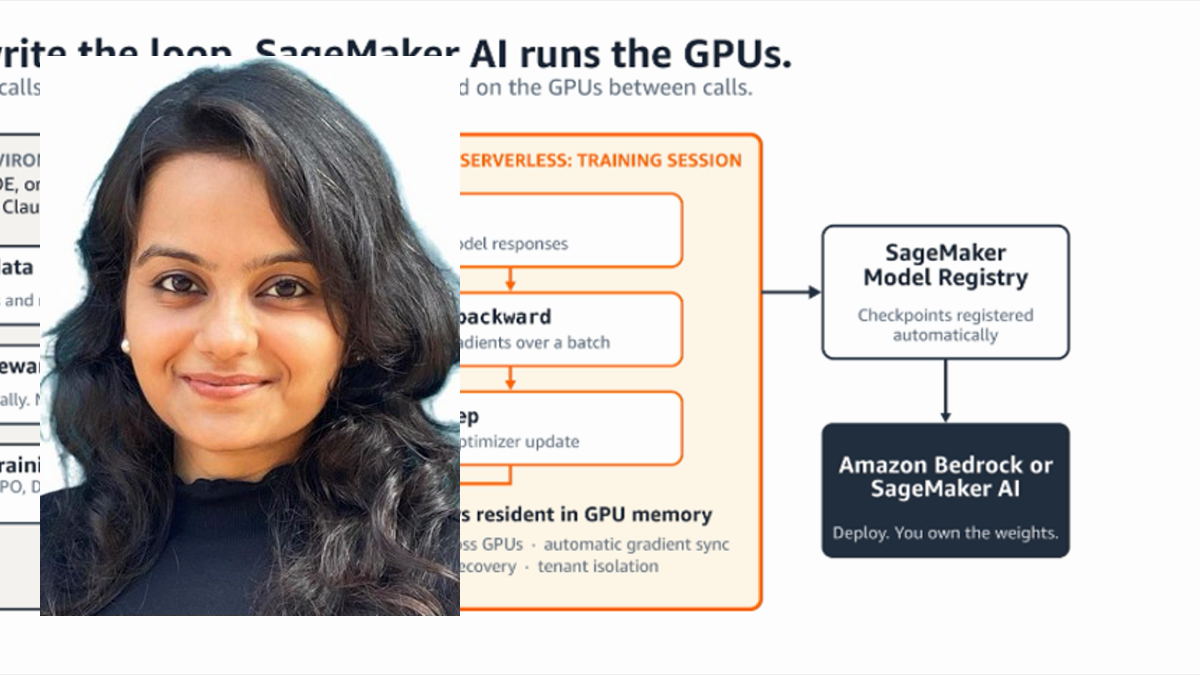


After large models are applied to enterprise operations, the most common issue is not that the models cannot answer general questions, but rather that they do not understand the company's own product catalog, claims processing rules, or multi-round service processes. On October 22nd, Amazon Web Services announced that the "training session" feature in its serverless model customization Amazon SageMaker AI was now officially available. Developers can write their own post-training loops, define loss functions, reward signals, and multi-round reinforcement learning processes; the platform is responsible for GPU distribution, distributed execution, fault recovery, and checkpoint saving. This solution alleviates the management burden of training infrastructure and does not decide for developers what tasks are worth training or what results are considered correct.
In the past, when using managed training services, companies often had to choose between two less than ideal options: either train completely according to the platform's preset processes, which was convenient but made it difficult to make detailed adjustments; or set up their own GPU clusters, which offered greater flexibility but required them to take on responsibilities such as resource scheduling, breakpoint recovery, and environment maintenance. Training Sessions aims to separate these two approaches, allowing teams to retain control over their algorithmic loops while delegating the underlying computational orchestration to the cloud platform. For teams that need to continuously iterate on their models based on business feedback, this division of labor is more targeted than simply adding another preset fine-tuning option.
Control the training logic, but still be responsible for data and evaluation.
The available methods listed in AWS include supervised fine-tuning, direct preference optimization, reinforcement learning based on verifiable rewards, AI feedback reinforcement learning, and multi-round reinforcement learning; parameter updates can be performed using LoRA or as a complete fine-tuning process. The choice of method is not the end of the story. If a customer service agent only learns to provide beautiful answers but is unable to maintain the order status after user modifications, the training task is still considered a failure. For multi-round scenarios, it is essential to design the environment, tool calls, final rewards, and failure feedback. The greater the freedom in the training loop, the more important the evaluation design becomes.
Training sessions allow companies to write their own reward functions, which means they can incorporate the business constraints that truly matter into the process. For example, a claims allocation model not only needs to determine the type of case but also must adhere to the boundaries of sufficient evidence and manual review; travel agents, in addition to providing itineraries, also need to avoid booking incorrect dates or exceeding budgets. However, if the reward function is not designed properly, the model may learn to focus on a score that is easy to calculate rather than improving the actual outcomes for users. Connecting the score with manual audits, offline testing, and post-live anomaly monitoring is a task that companies cannot outsource to the GPU scheduler.
The customer cases mentioned in the announcement also need to be read as intended. The person in charge of ImagineSoftware stated that the training sessions provide low-level interfaces for controlling forward, reverse, sampling, and optimization steps, which supports the advancement of their medical claims denial diversion model; this indicates that their team has verified the development experience of the platform, but it does not mean that compliance or accuracy rates have been universally guaranteed in the medical scenario. Another customer described the experience of multiple rounds of fine-tuning for knowledge graph tool calls and checkpoint recovery, which cannot be directly extrapolated to training benefits in other industries.
Cost models also have their limits. AWS states that billing is based on the amount of token processed, and there is no need to reserve capacity when the reward function evaluates in the customer environment. This approach is more flexible than maintaining GPU instances over the long term, but the cost still depends on the number of experiments, model size, input/output length, and repeated evaluations. If a team continuously reruns datasets of poor quality, "no need to manage GPU" does not necessarily mean that the total cost will be lower. Decision-makers need to compare the complete experimental cycles required to achieve the same quality goal, rather than just comparing the price of a single training run.
What should enterprises do for small-scale acceptance after it becomes officially available?
The product announcement lists several currently supported models, including gpt-oss-20b, gemma-4-31B-it, and two Qwen3 series models. The official availability of training sessions does not mean that any model, any region, or all custom operators are unconditionally supported. Before going live, it is necessary to verify the latest service documentation, regional availability, restrictions, and specific model versions. The development team also needs to distinguish between "training being able to run smoothly" and "models being able to be deployed securely": the latter involves changes in input distribution, permission constraints, monitoring, and rollback mechanisms.
AWS indicates that the session uses a role created by the customer, identified as IAM. It is possible to configure a KMS key and VPC. The training data and checkpoints are stored within a S3 bucket in the area selected by the customer. It is also stated that customer data or custom weights will not be used to train other models. These are control options provided by the platform and do not equate to an enterprise automatically completing internal security reviews. Who has the authority to initiate experiments, read raw data, export weights, or deploy models into production traffic requires the customer's own permissions and audit arrangements. Especially when dealing with personal data and sensitive business records, data minimization and retention periods should be specified in the go-live process.
A more cautious approach to experimentation is to start with a narrow task: fix the training and testing data, select an existing baseline model, and record the error categories, inference costs, and the rate of manual review; then use training sessions to make an interpretable post-training improvement. If the goal is multiple rounds of tool invocation, then test whether the task is completed, rather than just checking if the answers for a single round are smooth. Only when both quality improvement and the development and operation costs are reproducible is it worth expanding to more business lines. Failed samples should be retained to avoid the team misjudging the system's stability based on impressive cases.
This release represents that cloud services provide more detailed control points in the post-training phase, yet they do not announce "autonomous driving" for enterprise model customization. The easier it is to obtain underlying computing power, the more necessary it becomes to clearly define which data is reliable, what rewards are worth optimizing, and how to stop losses when performance declines. For teams that are truly ready to integrate AI agents into their business systems, what matters is not the disappearance of GPU from the interface, but whether the training cycle and production responsibilities are clearly separated.